
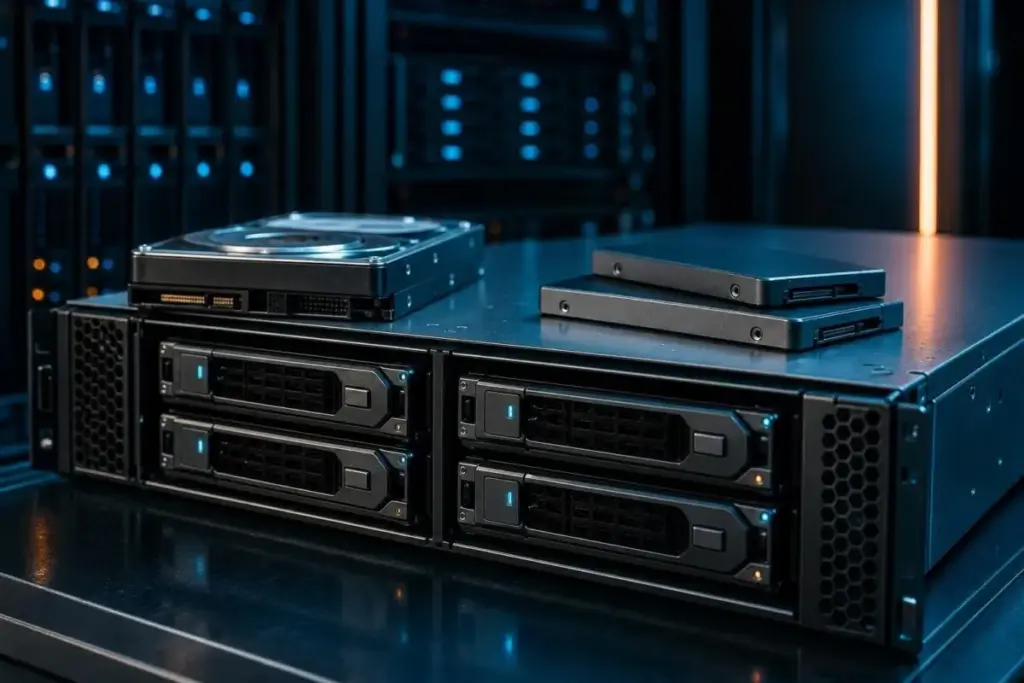
However, RAID 10 justifies this cost through its superior write performance. In parity-based systems like RAID 5 or RAID 6, every write operation requires the controller to calculate parity bits—a mathematical process that introduces latency. RAID 6, in particular, suffers from a significant "write penalty" because it must compute and write two separate parity blocks for every stripe. Industry models often suggest that RAID 10 carries a write penalty of approximately factor two, whereas RAID 6 can reach factor six.
While real-world performance is influenced by controller cache, stripe size, and the specific nature of the workload, RAID 10 is almost universally faster for small-block random writes. This makes it the preferred choice for transactional databases and heavy virtualization hosts where input/output operations per second (IOPS) are more valuable than raw terabytes.
The Mechanics of Recovery
Beyond daily performance, the true value of RAID 10 is revealed during a drive failure. When a disk in a RAID 10 array fails, the rebuild process is a straightforward mirror copy. The controller identifies the surviving member of the mirrored pair and clones its data onto a replacement drive.
This is fundamentally different from parity-based rebuilds. In a RAID 6 array, a rebuild requires the system to read data from all surviving disks and perform complex XOR calculations to "recreate" the missing data. This process is computationally expensive and puts a heavy I/O load on every drive in the array, often degrading performance for the end-user during the recovery period.
Data recovery specialists, including firms like DiskInternals, point out that RAID 10 rebuilds are generally faster and less stressful on the hardware. However, they caution that "faster" is relative. The actual duration of a rebuild is still bound by the physical speed of the drives and the volume of data being moved. While a mirror copy is efficient, it does not bypass the laws of physics or the limitations of the disk interface.
There is also a "hard boundary" to RAID 10’s fault tolerance. If two disks fail within the same mirrored pair, that data is permanently lost. Even if the other six disks in an eight-disk array are perfectly healthy, the loss of one specific pair breaks the stripe and destroys the volume. This highlights the importance of understanding independent versus correlated failures.
Mitigating Correlated Failures
RAID 10’s mathematical reliability assumes that disk failures are independent events. In reality, disks often share common points of failure, such as a backplane, a power supply, or a specific batch of firmware. If two disks from the same firmware batch are placed in the same mirror pair and operate under identical thermal conditions, they may fail at nearly the same time.
 Enterprise Tech & Infrastructure
Understanding the Architecture of Modern Storage: Why the ‘Flash vs. SSD’ Debate Misses the Point
In the rapidly evolving landscape of enterprise data management, the terminology used...
 Enterprise Tech & Infrastructure
GenAI Surge Triggers Record-Breaking Growth in Global Ethernet Switch and Router Markets
The massive wave of investment in Generative AI (GenAI) has long been...
 Enterprise Tech & Infrastructure
Upscale AI Challenges Nvidia’s Dominance with SkyHammer Scale-Up Fabric
For decades, the architecture of high-performance computing has been defined by a...







