
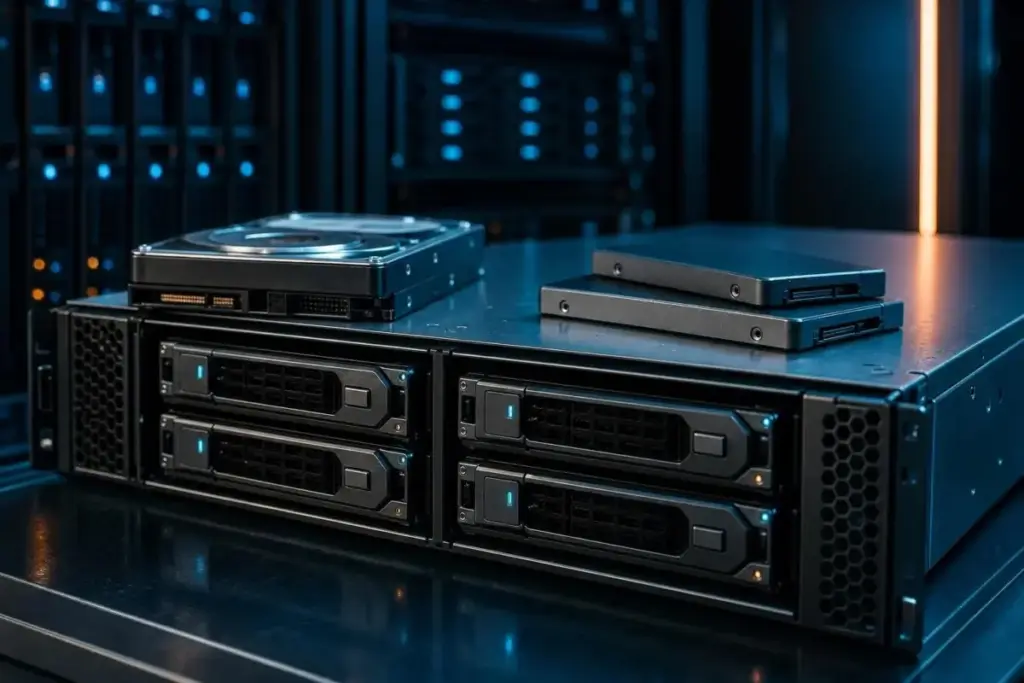
In the complex landscape of enterprise data storage, the selection of a RAID (Redundant Array of Independent Disks) level is rarely a simple matter of preference. It is a calculated decision that balances the competing demands of performance, capacity, and fault tolerance. Among the various configurations available to system architects, RAID 10 stands out as a premier choice for environments where high-speed input/output (I/O) and rapid recovery are non-negotiable requirements. By nesting two distinct RAID levels—mirroring for data safety and striping for throughput—RAID 10 provides a robust framework for mission-critical applications. However, this level of performance comes with a significant "capacity tax" and specific structural vulnerabilities that organizations must understand before committing their data to this topology.
At its core, RAID 10 is a nested array. While it is often referred to as a single entity, most modern implementations are built as RAID 1+0. This means that the system first creates mirrored pairs of disks (RAID 1) to ensure redundancy. These mirrored pairs are then treated as single logical units and striped together (RAID 0) to enhance speed. This configuration allows the array to leverage the best of both worlds: the immediate data availability of a mirror and the parallel processing capabilities of a stripe.
The primary appeal of RAID 10 lies in its efficiency during both normal operations and failure scenarios. Unlike parity-based systems such as RAID 5 or RAID 6, RAID 10 does not require the controller to perform complex mathematical calculations to generate parity bits every time data is written. This lack of parity-calculation overhead translates to superior write performance, making it an ideal candidate for write-intensive workloads. Furthermore, when a disk fails, the rebuild process is remarkably straightforward. Rather than recalculating lost data from parity information across the entire array, the controller simply copies the data from the surviving member of the mirrored pair to a new replacement disk. This simplicity reduces the mechanical and computational stress on the remaining drives during the recovery window.
Understanding the Hierarchy: RAID 1+0 vs. RAID 0+1
The internal logic of how a RAID 10 array is constructed—the "build order"—is not merely a technicality; it is a fundamental factor in how the system behaves under duress. The industry standard is RAID 1+0, or "striped mirrors." In this setup, the mirrors are the foundation. Because each mirrored pair is managed independently within the larger striped set, the array can theoretically survive the failure of multiple disks, provided that no two failed disks belong to the same mirrored pair. In an eight-disk array, for instance, you could lose up to four disks if they are distributed perfectly across the four pairs.
Conversely, RAID 0+1, or "mirrored stripes," follows the opposite logic. It first creates two large striped sets and then mirrors those sets against each other. While the components are the same, the failure behavior is significantly more fragile. If a single disk fails in one of the striped sets, that entire side of the mirror becomes degraded. If a second failure occurs on the opposite side of the mirror before the first is repaired, the entire array’s data is lost. Furthermore, structural limitations often prevent spare devices from being assigned to the underlying RAID 0 legs, as a standard stripe cannot tolerate the loss of even one device to begin a rebuild.
Because of these differences, IT professionals are cautioned to verify the specific topology of their hardware controllers. A datasheet that lists "RAID 10" support is often shorthand for RAID 1+0, but confirming the underlying architecture is essential for accurate risk assessment and disaster recovery planning.
The Capacity Tax and the Competitive Landscape
The most significant drawback of RAID 10 is its low capacity efficiency. Because every byte of data must be mirrored, the usable capacity of the array is always roughly 50% of the raw storage. For an organization utilizing eight 16 TB drives, a RAID 10 configuration would yield only 64 TB of usable space. In contrast, a RAID 6 configuration using the same drives would provide 96 TB of usable capacity, as it only reserves the equivalent of two drives for parity.
This capacity gap becomes even more pronounced as the number of drives in the array increases. However, the decision to use RAID 10 over RAID 6 or RAID 1 is usually driven by the nature of the workload rather than the cost of the hardware. The write-path difference is architectural: RAID 10 writes each block to both halves of a mirror with minimal latency. RAID 6, meanwhile, must compute and write two separate parity blocks for every stripe.
In a simplified performance model, RAID 10 carries roughly a 2x write penalty (writing the data twice), whereas RAID 6 can face a 6x penalty due to the "read-modify-write" cycle required for parity. While high-end controllers with large caches can mask some of this latency, the underlying physics remains. RAID 10 is the clear winner for sustained small-block random writes and latency-sensitive transactional workloads, such as Online Transaction Processing (OLTP) and dense virtualization environments. Organizations often adopt a tiered strategy, running RAID 10 on high-performance flash storage for active databases and virtual machines, while relegating RAID 6 to high-capacity hard disk drives for bulk storage and backups.
Failure Modes and the Reality of Rebuilds
When a drive in a RAID 10 array fails, the system enters a critical but manageable state. The rebuild process involves copying data from the surviving partner in the mirrored pair to a replacement disk. Because there is no parity recalculation involved, the process is generally faster and less taxing on the system’s overall performance than a parity-RAID rebuild. However, the duration of this process is not fixed; it depends heavily on the speed of the drives, the volume of data, and the specific throttling settings of the controller.
The primary danger in a RAID 10 environment is the "hard boundary" of its redundancy model. The array can survive one failed disk per mirrored pair, but if both disks in a single pair fail simultaneously, that specific segment of data is lost. Even if the other six disks in an eight-disk array are perfectly healthy, the loss of one pair renders the entire volume unrecoverable.
This risk highlights the difference between independent and correlated failures. RAID 10’s mathematical safety assumes that disks fail independently due to random mechanical wear. In reality, disks often share a common backplane, power supply, or firmware version. A power surge or a bug in a specific firmware batch could cause multiple disks to fail at once. To mitigate this, experts recommend a design-heavy approach: deliberately distributing mirror pairs across different physical backplanes or enclosures. This ensures that a single hardware failure at the enclosure level does not take out both members of a mirrored pair.
Software Implementation and Complex Configurations
The implementation of RAID 10 is not limited to hardware controllers. Software-defined storage options, particularly in the Linux ecosystem, offer a high degree of flexibility. Linux software RAID provides three distinct ways to deploy this level of redundancy. Administrators can manually stack RAID 1 and RAID 0 devices, or they can use the "complex" RAID 10 level via the mdadm utility.
The complex form of RAID 10 is particularly notable because it is not strictly a nested array. It allows for even or odd numbers of devices—a departure from the traditional requirement for even-numbered sets in RAID 1+0. It also offers various data layouts, such as "near," "far," and "offset." A "near" layout mimics standard RAID 10, while a "far" layout stripes data in a way that optimizes sequential read performance, potentially rivaling RAID 0 speeds while maintaining redundancy.
Furthermore, Logical Volume Manager (LVM) RAID 10 offers another layer of management, allowing for the creation and repair of arrays through standard LVM commands. However, these software solutions require diligent preparation. For instance, repairing a failed leg in an LVM RAID 10 setup requires a spare physical volume to be already available within the volume group. Without this foresight, the automated recovery features cannot engage, leaving the data at risk.
Hardware Controller Variations
While software RAID offers flexibility, hardware controllers from vendors like Broadcom and its MegaRAID family introduce their own set of proprietary rules and capabilities. These controllers are designed to handle massive scale, with some supporting spanned RAID 10 across as many as 240 drives. These high-end systems use "spans"—sub-arrays of mirrored pairs—to manage the load.
The thresholds for these configurations are often hard-coded into the controller’s firmware. For example, a controller might require a single-span RAID 1 for smaller drive counts but automatically shift to multi-span configurations once the drive count exceeds a certain threshold, such as 32 or 36 drives. These vendor-specific behaviors mean that an architecture designed for one hardware platform may not be directly transferable to another.
Strategic Considerations for the Modern Data Center
As flash storage continues to drop in price and increase in density, the conversation around RAID 10 is evolving. While SSDs significantly reduce rebuild times and offer massive IOPS, the 50% capacity loss remains a significant financial consideration. In large-scale all-flash deployments, some organizations are moving away from RAID 10 in favor of erasure coding or software-defined replication, which can provide similar levels of resilience with better capacity efficiency.
Ultimately, RAID 10 remains a specialized tool. It is the preferred solution when the cost of downtime and the need for absolute performance outweigh the cost of raw storage. Whether it is supporting a high-traffic SQL Server or a cluster of virtual desktops, RAID 10 provides a predictable, high-performance foundation. However, its effectiveness is entirely dependent on proper implementation—from the choice of RAID 1+0 over 0+1 to the physical distribution of drives across power domains. In the world of enterprise storage, RAID 10 is not a "set it and forget it" solution, but rather a sophisticated architecture that requires careful planning and ongoing management.
 Enterprise Tech & Infrastructure
Navigating the Hidden Financial Mechanics of Amazon S3: Strategies for Enterprise Cost Optimization
In the landscape of modern enterprise cloud architecture, Amazon S3 has long...
 Enterprise Tech & Infrastructure
Navigating the Financial Realities of Enterprise Cloud Storage: A Comprehensive Analysis of Amazon S3 Cost Management
In the rapidly evolving landscape of enterprise cloud infrastructure, the management of...
 Enterprise Tech & Infrastructure
Upscale AI Challenges Nvidia’s Scale-Up Dominance with SkyHammer Fabric and $2 Billion Valuation
For decades, the architecture of high-performance computing was defined by a fiercely...






