
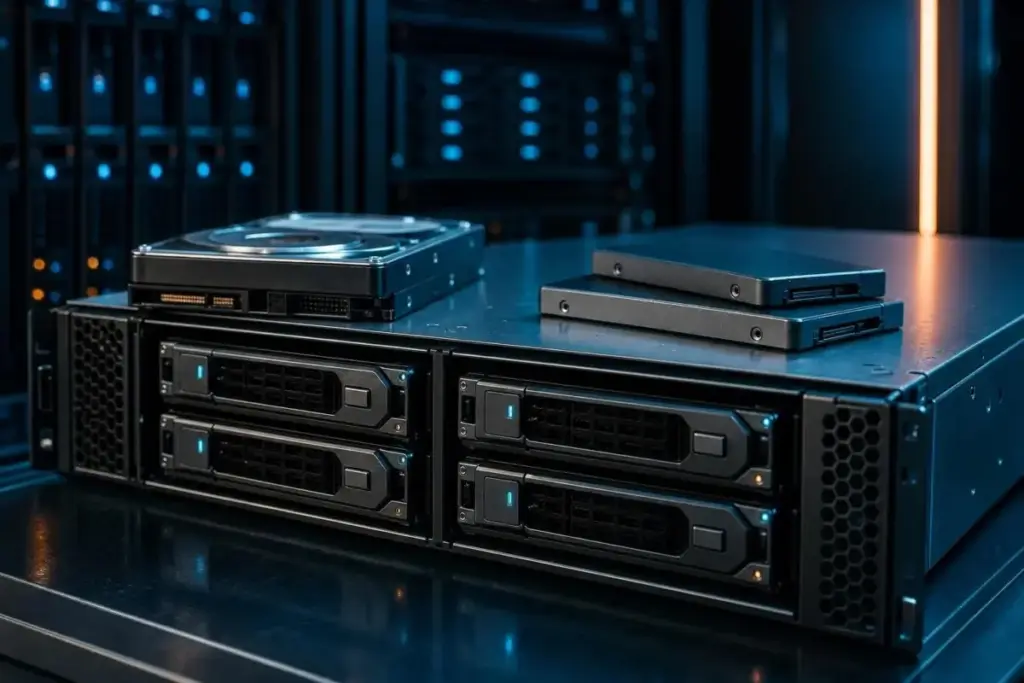
This capacity gap becomes even more pronounced as the number of drives in the array increases. However, the decision to use RAID 10 over RAID 6 or RAID 1 is usually driven by the nature of the workload rather than the cost of the hardware. The write-path difference is architectural: RAID 10 writes each block to both halves of a mirror with minimal latency. RAID 6, meanwhile, must compute and write two separate parity blocks for every stripe.
In a simplified performance model, RAID 10 carries roughly a 2x write penalty (writing the data twice), whereas RAID 6 can face a 6x penalty due to the "read-modify-write" cycle required for parity. While high-end controllers with large caches can mask some of this latency, the underlying physics remains. RAID 10 is the clear winner for sustained small-block random writes and latency-sensitive transactional workloads, such as Online Transaction Processing (OLTP) and dense virtualization environments. Organizations often adopt a tiered strategy, running RAID 10 on high-performance flash storage for active databases and virtual machines, while relegating RAID 6 to high-capacity hard disk drives for bulk storage and backups.
Failure Modes and the Reality of Rebuilds
When a drive in a RAID 10 array fails, the system enters a critical but manageable state. The rebuild process involves copying data from the surviving partner in the mirrored pair to a replacement disk. Because there is no parity recalculation involved, the process is generally faster and less taxing on the system’s overall performance than a parity-RAID rebuild. However, the duration of this process is not fixed; it depends heavily on the speed of the drives, the volume of data, and the specific throttling settings of the controller.
The primary danger in a RAID 10 environment is the "hard boundary" of its redundancy model. The array can survive one failed disk per mirrored pair, but if both disks in a single pair fail simultaneously, that specific segment of data is lost. Even if the other six disks in an eight-disk array are perfectly healthy, the loss of one pair renders the entire volume unrecoverable.
This risk highlights the difference between independent and correlated failures. RAID 10’s mathematical safety assumes that disks fail independently due to random mechanical wear. In reality, disks often share a common backplane, power supply, or firmware version. A power surge or a bug in a specific firmware batch could cause multiple disks to fail at once. To mitigate this, experts recommend a design-heavy approach: deliberately distributing mirror pairs across different physical backplanes or enclosures. This ensures that a single hardware failure at the enclosure level does not take out both members of a mirrored pair.
Software Implementation and Complex Configurations
The implementation of RAID 10 is not limited to hardware controllers. Software-defined storage options, particularly in the Linux ecosystem, offer a high degree of flexibility. Linux software RAID provides three distinct ways to deploy this level of redundancy. Administrators can manually stack RAID 1 and RAID 0 devices, or they can use the "complex" RAID 10 level via the mdadm utility.
 Enterprise Tech & Infrastructure
Navigating the Shift to Software-Defined Storage: Essential Strategies for Modern Enterprise Data Management
The landscape of enterprise data management is undergoing a fundamental transformation as...
 Enterprise Tech & Infrastructure
Bridging the Gap in Data Center Convergence: The Evolving Role of Fibre Channel over Ethernet
As data centers face unprecedented pressure to handle massive workloads driven by...
 Enterprise Tech & Infrastructure
Navigating the Hidden Complexities of Amazon S3 Cost Management for the Enterprise
The financial management of cloud storage has evolved into a discipline that...







