
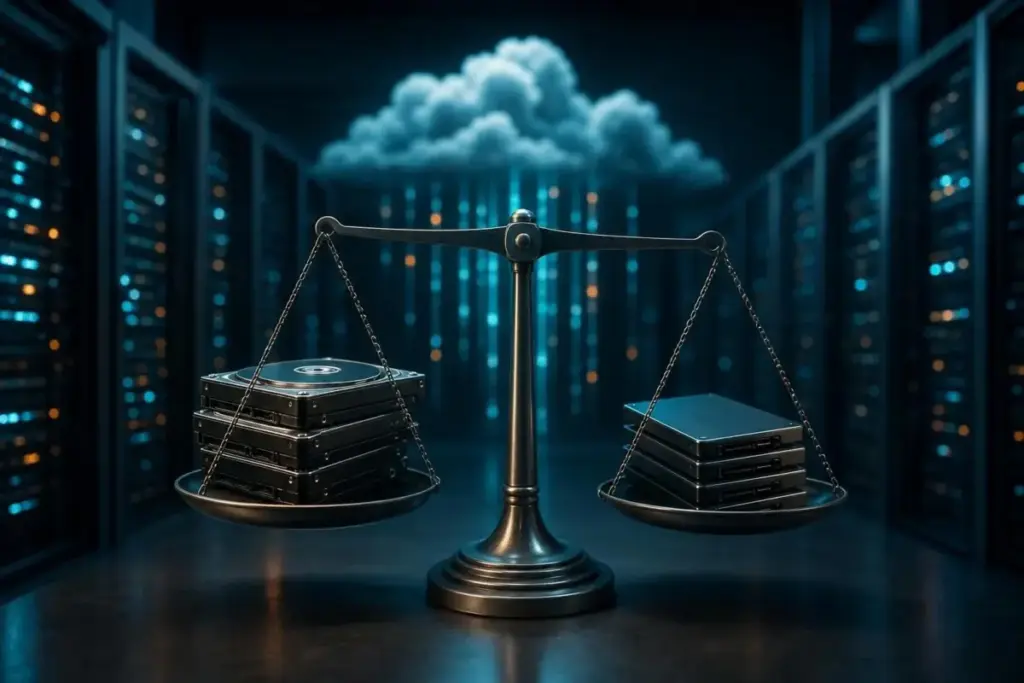
For enterprise IT leaders and cloud architects, the promise of Amazon S3 has always been its scalability and perceived simplicity. However, as data footprints grow into the petabyte scale, many organizations are discovering a sobering reality: the monthly bill rarely aligns with the simple per-gigabyte rates listed on the marketing pages. The single most significant driver of S3 overspend in the modern enterprise is the tendency to treat the storage class rate as the entirety of the cost. In practice, the actual expenditure is a complex sum of storage volume, request counts, transition fees, retrieval charges, and data transfer costs.
To manage these costs effectively, organizations must look beyond the base rate and understand the mechanical behavior of the AWS ecosystem. For data with a predictable aging curve—where information is accessed frequently at birth and rarely thereafter—S3 Lifecycle rules that transition objects to colder tiers like Standard-Infrequent Access (Standard-IA) or Glacier are the standard recommendation. Conversely, for workloads where access patterns are erratic, shifting, or entirely unknown, AWS advocates for S3 Intelligent-Tiering. This class is designed to automate savings independent of object size or retention periods, yet even this automated solution requires a rigorous evaluation against regional pricing and specific workload profiles.
The Multi-Faceted Equation of Cloud Storage Spend
Enterprise S3 expenditure is never a single line item; it is a cumulative total of several distinct operational metrics. To build an accurate cost model, one must account for storage GB-months across various classes, but also the heavy toll of request costs. Every PUT, COPY, LIST, and GET operation carries a price tag. Furthermore, the act of moving data between tiers—lifecycle transitions—is billed per object. For organizations managing billions of small files, these transition requests can occasionally exceed the actual storage savings gained by moving to a cheaper tier.
Beyond requests, retrieval charges and data transfer fees often represent the "hidden" portion of the iceberg. Retrieval from Glacier tiers, for instance, is metered separately through Bulk or Expedited requests, and the data itself is charged per gigabyte as it is moved back to a readable state. Data transfer is another layer of complexity, with AWS tracking outbound internet egress, inbound transfers, and regional transfers to other AWS services like EC2 as distinct usage types.
Optional features, while providing high value, also add to the bill. Intelligent-Tiering monitoring fees, S3 Inventory listings, Multi-Region Access Points (MRAP) routing, and S3 Metadata processing are all metered. These costs appear as separate line items in usage reports, and failing to model them can lead to significant budgetary discrepancies. Before committing to a storage strategy, experts recommend running a model against a representative bucket—for example, 10 million objects averaging 2 MB—and pricing it through multiple scenarios: Standard with Lifecycle rules, straight Intelligent-Tiering, and Intelligent-Tiering with Archive Access enabled.
Profiling Data as a Prerequisite for Efficiency
The first step in any cost-control initiative is a comprehensive profiling of the data itself. Before adjusting storage class settings, administrators must segment objects by size, access frequency, and retention requirements. A critical change implemented by AWS in September 2024 has altered the default behavior of Lifecycle rules: objects smaller than 128 KB are now prevented from transitioning to any storage class automatically. While this protects users from the high per-object overhead of moving tiny files, configurations built before this date may still follow old behaviors unless manually modified.
Utilizing tools like S3 Storage Lens or S3 Inventory is essential to identify how much capacity sits below that 128 KB threshold. AWS is transparent about the reasoning: for smaller objects, the cost of the transition request often outweighs any potential storage savings. If an organization has inherited older buckets, a retrospective audit is necessary to ensure that legacy lifecycle policies are not inadvertently inflating the bill.
Special attention must also be paid to versioned buckets and the use of Object Lock. In buckets where versioning is enabled, simply expiring a current version does not delete the data; it creates a delete marker. These markers, along with previous versions, continue to count as objects and contribute to both storage and request counts. Without a secondary Lifecycle rule to clean up expired delete markers and incomplete multipart uploads, an organization can find itself paying for "ghost" data indefinitely.
 Enterprise Tech & Infrastructure
Navigating the Shift to Software-Defined Storage: Essential Strategies for Modern Enterprise Data Management
The landscape of enterprise data management is undergoing a fundamental transformation as...
 Enterprise Tech & Infrastructure
Upscale AI Challenges Nvidia’s Dominance with SkyHammer Scale-Up Fabric
For decades, the architecture of high-performance computing has been defined by a...
 Enterprise Tech & Infrastructure
Navigating the Financial Realities of Enterprise Cloud Storage: A Comprehensive Analysis of Amazon S3 Cost Management
In the rapidly evolving landscape of enterprise cloud infrastructure, the management of...







