
For decades, the world’s leading CPU manufacturers have maintained a fiercely proprietary grip on the interconnects used to link multiple processors into shared memory clusters. Whether it was the SMP (Symmetric Multiprocessing) or NUMA (Non-Uniform Memory Access) designs of the past, each vendor developed its own unique "glue" to make a collection of chips behave like a single, massive compute engine. Despite the best efforts of industry consortia like CCIX and CXL to create a universal standard for memory sharing, these attempts largely faltered. Customers may have craved interoperability, but the reality was that few workloads required mixing different CPU architectures, and vendors preferred to innovate on their own schedules without waiting for a standards body to approve new features.
Today, that same battle for proprietary control has shifted from the CPU to the GPU and the XPU. As artificial intelligence workloads demand ever-larger clusters of accelerators, the industry is witnessing the birth of what is now commonly referred to as scale-up networking. At the center of this movement is Nvidia, which has leveraged its proprietary NVLink and NVSwitch technologies to create a dominant position in the AI infrastructure market. However, a well-funded challenger, Upscale AI, is emerging with a vision of a more open, Ethernet-based future for AI fabrics.
The stakes are immense. Nvidia currently charges a significant premium for its NVSwitch and NVLink ports, which provide the high bandwidth and low latency required to connect up to 72 GPUs in a single shared memory domain—a configuration Nvidia calls the NVL72 rackscale machine. While Nvidia has recently begun a "NVLink Fusion" effort, allowing custom CPU and accelerator makers to license NVLink ports to hook into Nvidia’s memory space, it remains a tightly controlled ecosystem. Nvidia has yet to allow customers to build their own independent shared memory systems using their own CPUs and XPUs while merely licensing the NVLink protocol.
This environment of proprietary lock-in is precisely why Upscale AI has captured the attention of the industry and venture capitalists alike. Since its initial $200 million Series A funding round in January, the company’s momentum has accelerated rapidly. Upscale AI has now raised a total of $500 million, seeing its valuation double to $2 billion in less than a year. Its workforce has similarly expanded to over 300 employees, many of whom are veterans of the high-performance networking and systems world. This week, the company’s leadership provided a closer look at "SkyHammer," the scale-up switch ASIC that sits at the heart of its strategy to disrupt the AI networking status quo.
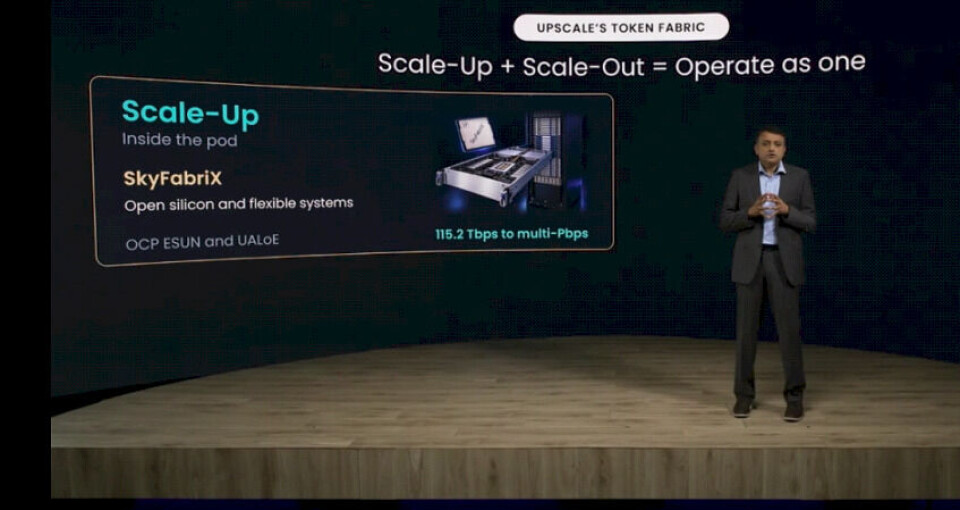
The SkyHammer ASIC is designed to provide an alternative to the proprietary silos currently dominating the market. According to disclosures from Upscale AI’s executive chairman Rajiv Khemani and CEO Barun Kar, the SkyHammer chip boasts an aggregate bandwidth of 115.2 Tb/sec. This figure places the ASIC on equal footing with the highest-end scale-out networking silicon from industry giants like Broadcom, Cisco, and Nvidia. Furthermore, the company’s SkyFabriX architecture is designed to eventually support switch gear with aggregate bandwidth measured in the multiple petabits per second.
Such massive bandwidth is typically achieved by ganging multiple ASICs together within a single switch. This "baby two-tier" approach, often utilized by companies like Broadcom and Meta, allows for a doubling of port bandwidth by using a cluster of independent ASICs where some chips act as downlinks and others act as internal couplers. While this can increase latency due to additional port hops, it is an economically efficient way to scale. Upscale AI appears to be following a similar trajectory, though it has not yet provided a detailed roadmap for future iterations of the SkyHammer silicon.
When it comes to memory domain scalability, SkyHammer is designed to support up to 576 accelerators within a single networking tier. By utilizing multiple tiers, the fabric can scale to support thousands of devices. For comparison, the UALink consortium—a rival standards-based effort—is aiming for 1,024 XPUs in a single tier, while Nvidia’s upcoming "Rubin Ultra" generation is expected to push NVSwitch to 1,152 GPUs across a multi-tier network.
However, a raw comparison of bandwidth reveals a significant gap between Upscale AI’s current offering and Nvidia’s top-tier hardware. If one calculates the bandwidth per device in a 576-accelerator SkyHammer configuration, each device receives approximately 200 Gb/sec. This is considerably lower than the 1.8 TB/sec offered by Nvidia’s NVSwitch 5/NVLink 5 generation used in the Grace-Blackwell NVL72 systems, and even further behind the 3.6 TB/sec promised for the Vera-Rubin generation.
Despite this disparity in raw throughput, Upscale AI argues that bandwidth is not the only metric that matters in the AI era. For AI inference workloads, in particular, the predictability of latency is often more critical than the sheer volume of data being moved. Arvind Srikumar, Senior Vice President of Product and Marketing at Upscale AI, emphasizes that the company has built "predictable jitter" and "transmission reliability" directly into the ASIC.
Srikumar notes that while traditional Ethernet fabrics often rely on a fixed pipeline arrangement with limited parallelism, SkyHammer was designed from a "clean sheet of paper." The goal was to avoid the pitfalls of retrofitting existing Ethernet protocols for scale-up tasks. Instead, SkyHammer utilizes a mechanism to ensure the fabric is 100 percent lossless within the domain, providing what the company calls "reliable and predictable latency."
Technically, SkyHammer is an Ethernet-based switch ASIC, but it runs specialized protocols such as UALoE (UALink over Ethernet) and ESUN. This choice highlights a broader industry trend: the convergence of Ethernet and high-performance interconnects. While InfiniBand has long been the gold standard for low-latency HPC and AI training, Ethernet is rapidly closing the gap. With the emergence of the Ultra Ethernet Consortium (UEC) specifications, many believe Ethernet will eventually supersede InfiniBand due to its superior ability to scale out and its broader ecosystem of support.
Upscale AI is also playing a strategic game with its software stack. The company’s SkyOS network operating system is an AI-optimized version of SONiC (Software for Open Networking in the Cloud), the open-source OS and Switch Abstraction Interface (SAI) originally created by Microsoft. SONiC has become a de facto standard for hyperscalers, and by building on this foundation, Upscale AI ensures its technology is compatible with existing datacenter management tools.
In a move that underscores the complexity of the current market, Upscale AI has actually partnered with Nvidia for its scale-out fabric needs. The company will acquire Nvidia’s Spectrum-X Ethernet ASICs to build its own scale-out switches, porting SkyOS to run on Nvidia’s hardware. This allows Upscale AI to offer a unified management experience via its SkyCMD orchestration tool, which can oversee both the scale-up SkyFabriX and the scale-out Spectrum-X networks as a single entity.
This unified approach allows customers to mix and match CPUs, GPUs, and XPUs from different vendors, provided they are front-ended by a compatible NIC or DPU. However, a significant hurdle remains: Nvidia does not currently support SkyHammer or SkyOS as a scale-up alternative to NVSwitch. For customers who are already locked into the Nvidia ecosystem for training large-scale models, switching to an alternative scale-up fabric is not yet a viable option.
This leaves companies like AMD in a pivotal position. AMD is heavily reliant on open standards and third-party networking options to provide a competitive alternative to Nvidia’s integrated stacks. There is speculation that AMD might eventually seek to acquire a company like Upscale AI to secure its own scale-up networking technology and capture a larger share of the infrastructure spend.
As the industry moves toward the next generation of AI hardware, the battle between proprietary and open networking will only intensify. Nvidia may eventually choose to adopt industry-standard scale-up networks for inference workloads where its market lock is less absolute, while maintaining its proprietary grip on training. Conversely, if Upscale AI can prove that its "predictable latency" model offers superior performance for real-world AI applications, the pressure on Nvidia to open its ecosystem will continue to mount. For now, Upscale AI is betting that the market’s desire for competition and lower costs will provide a path for its SkyHammer silicon to become the "universal glue" that the industry has sought for decades.
 Enterprise Tech & Infrastructure
Protecting the Enterprise Perimeter: The Evolving Security Challenges of DAS and NAS Storage
In the modern enterprise landscape, data is often described as the new...
 Enterprise Tech & Infrastructure
Navigating the Abstraction Layer: Strategic Best Practices for Software-Defined Storage Deployment
As the modern enterprise grapples with an unprecedented explosion of data, the...
 Enterprise Tech & Infrastructure
Navigating the Shift to Software-Defined Storage: Expert Strategies for Enterprise Success
The modern enterprise data center is undergoing a fundamental transformation, driven by...







