
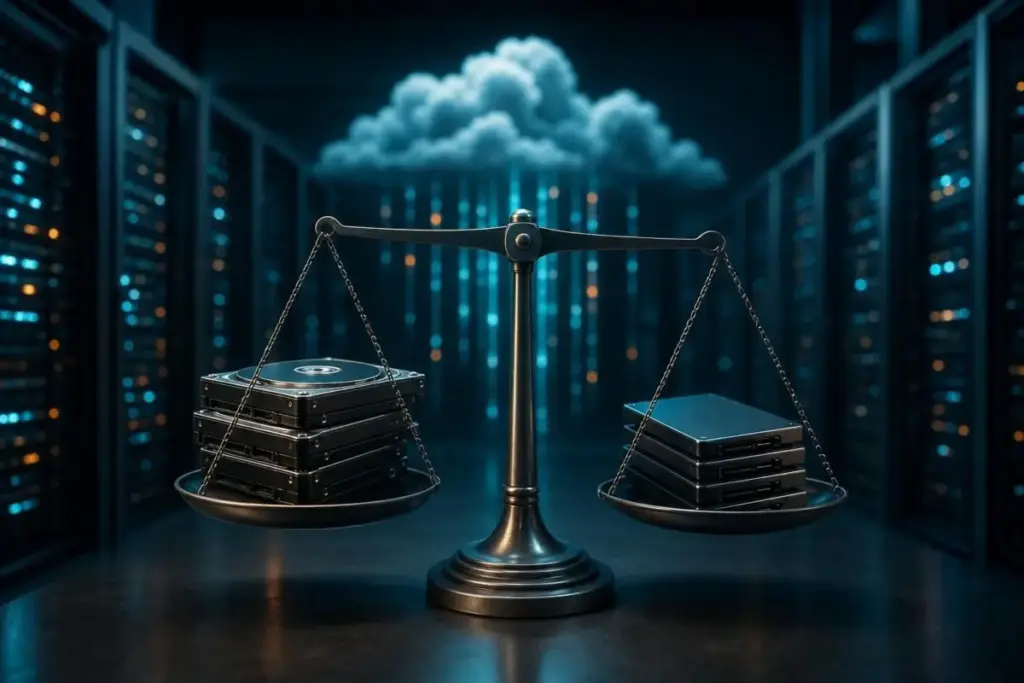
In the modern enterprise landscape, the Amazon Simple Storage Service (S3) has long been regarded as the bedrock of scalable data management. However, as data volumes swell into the petabyte range, many organizations are discovering that their monthly cloud invoices are far more complex than a simple calculation of gigabytes stored. Industry experts and cloud financial management professionals increasingly warn that the single biggest driver of S3 overspend is the tendency to treat the per-gigabyte rate as the entirety of the bill. In reality, the true cost of ownership is a multifaceted equation that includes storage duration, request volumes, transition fees, retrieval charges, and data transfer costs.
To achieve meaningful cost control, organizations must move beyond marketing headlines and engage with the granular mechanics of AWS service architecture. The challenge lies in the fact that AWS offers a wide array of storage classes and automation tools, each designed for specific access patterns. Choosing the wrong path—or failing to model the workload accurately—can lead to scenarios where the cost of moving or managing data actually exceeds the savings gained from a lower storage rate.
Building the Comprehensive Cost Equation
Enterprise-grade S3 expenditure is rarely a single line item; it is a sum of several distinct usage types that appear across AWS billing and usage reports. According to AWS documentation on understanding billing reports, these costs are categorized into several critical buckets. First is the base storage rate, measured in GB-months, which varies significantly between tiers like S3 Standard and S3 Glacier Deep Archive.
However, the storage rate is often eclipsed by request costs. Every action taken on an object—whether it is a PUT, COPY, LIST, or GET—incurs a fee. Even the automated processes intended to save money, such as lifecycle transition requests, are billed on a per-object basis. For workloads characterized by high churn or millions of small files, these request fees can become the dominant cost driver.
Furthermore, retrieval charges add another layer of complexity. While S3 Standard offers free retrievals, tiers like Standard-Infrequent Access (Standard-IA) and the various Glacier classes charge for every gigabyte read. Within the Glacier ecosystem, these costs are further segmented by the speed of retrieval, with "Expedited" requests carrying a significant premium over "Bulk" or "Standard" speeds.
Data transfer remains perhaps the most scrutinized and often underestimated component of the bill. Usage reports track outbound transfer to the internet, inbound transfer, and regional transfers between S3 and other AWS resources like EC2 instances. In many multi-region architectures, cross-region replication and egress fees can become the largest single expense, often overshadowed in initial cost models that focus purely on storage rates. Optional features, including S3 Inventory listings, Multi-Region Access Points (MRAP) routing, and Intelligent-Tiering monitoring, further contribute to the final tally, appearing as separate line items that require individual oversight.
The Importance of Data Profiling and the 128 KB Threshold
Before an organization selects a storage class or implements an automation rule, it must first profile its data. This involves segmenting objects by average size, access frequency, and required retention periods. A critical technical pivot occurred in September 2024, when AWS updated its default Lifecycle behavior. Under the new rules, objects smaller than 128 KB are prevented from transitioning to any storage class automatically.
This change was designed to protect customers from a common "cost trap." Because transition requests are charged per object regardless of size, the cost of moving a very small file can be higher than the storage savings achieved over its entire lifetime. AWS documentation explicitly notes that for smaller objects, transition costs can frequently outweigh the benefits. Organizations inheriting older buckets must be particularly vigilant, as configurations built before the September 2024 update may still follow legacy behaviors unless manually modified.
Tools like S3 Storage Lens and S3 Inventory have become essential for identifying how much capacity sits below this 128 KB threshold. Beyond size, administrators must also account for versioned buckets and Object Lock usage. In buckets where versioning is enabled, simply expiring a current version does not delete the data; it creates a "delete marker," which continues to count as an object. Without a secondary lifecycle rule to clean up non-current versions and expired delete markers, storage and request counts can inflate indefinitely, leading to "ghost" costs that are difficult to track without granular governance tooling.
Strategic Automation: Lifecycle Rules vs. Intelligent-Tiering
When it comes to managing data at scale, AWS provides two primary paths: manual scheduling via Lifecycle rules and automated management via S3 Intelligent-Tiering. These are not mutually exclusive alternatives, but rather different tools that can be layered to suit specific needs.
Lifecycle rules serve as a scheduling mechanism. They allow administrators to define a timeline—for example, moving data to Standard-IA after 30 days and then to Glacier Flexible Retrieval after a year. This approach is ideal for data with a known aging curve, where access patterns are predictable and decline over time. One nuance often overlooked is that billing changes apply the moment a Lifecycle rule is satisfied, even if the physical movement of the data has not yet finished. However, transitions into Glacier tiers carry a specific 40 KB per-object overhead (8 KB at Standard rates and 32 KB at the Glacier rate), which must be factored into any break-even analysis.
In contrast, S3 Intelligent-Tiering is a storage class in its own right, designed for data with unknown or shifting access patterns. It automatically moves data between three low-latency tiers based on access frequency, with no retrieval charges or fees for moving data between these tiers. While this offers immense operational convenience, it comes with a trade-off: a monthly per-object monitoring and automation fee. For portfolios containing millions of objects, this "small" fee can accrue into a substantial monthly expense.
The decision between these two often hinges on predictability. If the workload is a new data lake or an analytics pipeline with unproven access patterns, Intelligent-Tiering acts as insurance against manual mis-tiering. If the workload is a stable archive with a clear deletion policy, Lifecycle rules offer a more direct path to cost reduction.
Navigating Minimum Durations and the "One-Way Street"
One of the most common pitfalls in S3 cost management is ignoring the minimum storage duration requirements associated with lower-cost tiers. Standard-IA and One Zone-IA require a 30-day minimum commitment, while Glacier Instant and Flexible Retrieval require 90 days. Glacier Deep Archive, the lowest-cost tier, requires a 180-day commitment.
If an object is deleted, overwritten, or transitioned to another class before this minimum duration is met, AWS charges a prorated fee for the remainder of the period. This "early exit" penalty can quickly evaporate any projected savings if data churn is higher than expected. Furthermore, the transition paths for the coldest storage tiers are often a "one-way street." For instance, data in Glacier Flexible Retrieval can be moved to Deep Archive via a Lifecycle rule, but data already in Deep Archive cannot be converted back to a warmer tier through automation. Restoring such data requires a manual process to create a temporary copy, which introduces both cost and latency.
Governance, Tagging, and Verification
Effective cost control is impossible without robust governance. AWS recommends using cost-allocation tags to ensure that bucket spend is correctly attributed to specific applications or departments. However, administrators should be aware of the operational delays inherent in the system: after a tag is applied, it can take up to 24 hours to appear in the cost allocation console and another 24 hours to become active for billing reports.
To verify that lifecycle actions are actually running as intended, AWS suggests relying on S3 Storage Lens dashboards rather than standard CloudWatch metrics. Storage Lens provides a more comprehensive view of daily storage changes and allows for cross-checking with S3 Inventory to verify the actual access tier where objects have landed.
Additionally, for enterprises utilizing the AWS Service Catalog AppRegistry, the awsApplication tag is automatically applied and activated for cost reporting. While this is a useful convenience layer for tracking total application spend, it is not a substitute for a deliberate, organization-wide tagging taxonomy.
Conclusion: Modeling Before Commitment
Ultimately, the path to S3 cost optimization is paved with data-driven modeling rather than general assumptions. Any specific savings figure presented in a budget meeting should be based on a workload-specific model run against current regional pricing. This model must account for the unique object-size distribution of the bucket, the anticipated retrieval frequency, and the potential for early-exit penalties.
For high-request, high-transfer, or heavily encrypted workloads, the storage-class delta is often just the tip of the iceberg. By performing a rigorous analysis of data transfer patterns, request volumes, and the technical limitations of each storage tier, organizations can transform S3 from a source of "bill shock" into a finely tuned, cost-effective component of their cloud infrastructure. In the world of AWS storage, the most expensive choice is the one made without a full understanding of the underlying math.
 Enterprise Tech & Infrastructure
Upscale AI Challenges Nvidia’s Dominance with SkyHammer Scale-Up Fabric and Unified AI Networking
The history of the semiconductor industry is littered with the remains of...
 Enterprise Tech & Infrastructure
Upscale AI Challenges Nvidia’s Dominance with SkyHammer Scale-Up Fabric
For decades, the architecture of high-performance computing has been defined by a...
 Enterprise Tech & Infrastructure
Cadence Systems Accelerates Chip Design Revolution with Maestro AI and Specialized Super Agents
The landscape of semiconductor engineering is undergoing a fundamental transformation as generative...







