
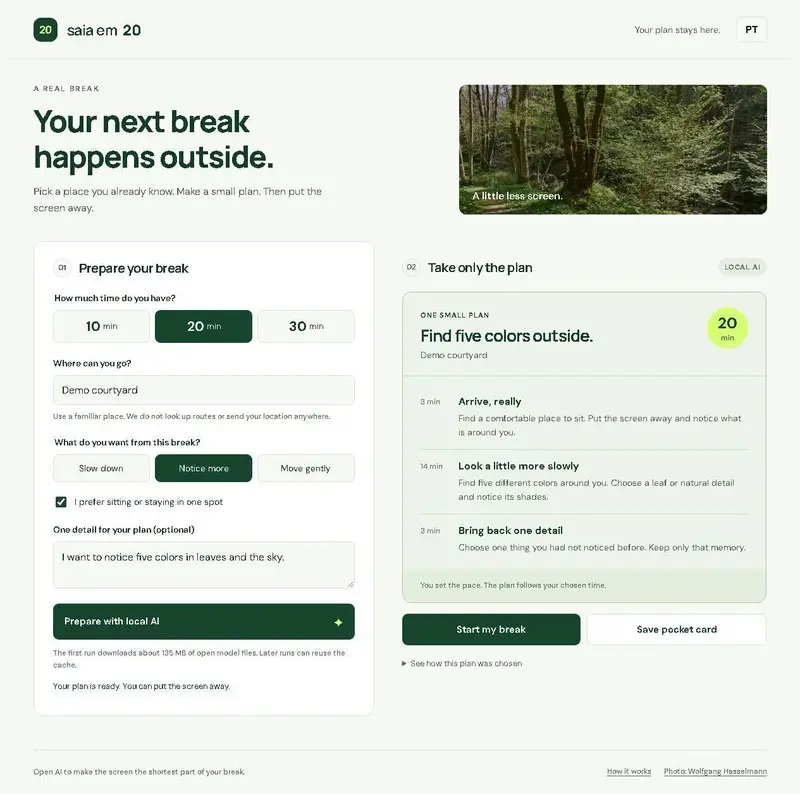
The developer notes that the initial AI setup requires an internet connection to handle a substantial download of model assets. This setup is intended to be completed while the user is still indoors. Once the model is cached in the browser’s storage, the inference can happen locally, aligning with the project’s goal of facilitating a quick exit to the outdoors.
Code
The project’s public repository serves as a testament to modern open-source development practices. The codebase is supported by a suite of ten automated tests that verify critical application boundaries. these tests ensure that activity eligibility is calculated correctly and that the application handles text input safely, preventing common vulnerabilities.
The efficiency of the development pipeline is highlighted by the project’s GitHub Actions integration. A full workflow—which involves installing locked dependencies, running the test suite, building the application, and uploading the browser bundle—is completed in a remarkably short twenty-four seconds. This rapid deployment cycle is crucial for open-source contributors who need to iterate quickly. Beyond the automated tests, the developer has provided separate browser evidence to confirm that model execution occurs via WebAssembly (WASM), ensuring that the AI inference is truly happening on the client side rather than a remote server.

How I Built It
The technical journey of "Outside in 20" provides a fascinating look into the challenges of deploying small-scale AI models on the web. The developer’s initial approach utilized SmolLM2-135M, a small language model, with a system of constrained outputs. While this model was capable of producing valid activity IDs, it suffered from a significant "mode collapse" or bias issue. Regardless of the user’s input, the model repeatedly selected the first available activity in the list. This highlighted a common pitfall in AI development: a successful format check (the model providing a valid ID) can often mask a fundamental failure in the recommendation logic.
To resolve this, the developer pivoted to a different class of AI: the embedding model. Specifically, the project transitioned to using multilingual-e5-small, an open-source model designed to transform text into numerical representations known as embeddings. These embeddings allow the application to mathematically compare the similarity between a user’s preference and the curated activities in the catalogue.
The application utilizes the Xenova q8 conversion of the original intfloat model, running it through the Transformers.js library. This setup allows the model to execute within the browser via WebAssembly. The resulting architecture follows a clear four-step flow: the user provides input, the model generates an embedding for that input, the system calculates the similarity against the activity catalogue, and the most relevant, eligible activity is presented.
This shift to an embedding-based approach ensures that the model cannot "hallucinate" or invent activities that do not exist in the curated list. It also ensures that eligibility filters—such as those for mobility constraints—are strictly enforced. The scores displayed in the app represent mathematical similarity rather than a "confidence percentage," providing a more transparent view of how the AI is making its decisions. Recent browser checks confirmed the model’s accuracy, successfully distinguishing between requests for "bird sounds" in Portuguese and "textural observations" in English, while consistently respecting "seated-only" filters when requested.
 Software Development & Scripting for IT
Bridging the Gap Between Canvas and Cafe: Developer Builds Local AI Suite to Help Madrid Artist Manage Exhibitions
In the bustling cultural landscape of Madrid, where neighborhood cafes and local...
 Software Development & Scripting for IT
CogniRunner Unveils AI-Driven License Management and Workflow Validation for Atlassian Cloud Ecosystem
The landscape of enterprise software management is undergoing a significant shift as...
 Software Development & Scripting for IT
The Architecture Gap: Why AI Coding Agents Are Generating More Code but Less Software
In the modern landscape of software development, a peculiar paradox has begun...







