
As the global demand for data storage continues to skyrocket, driven largely by the insatiable needs of artificial intelligence and high-performance computing, the industry is approaching a fundamental breaking point in how it protects that information. VAST Data, a leader in AI storage infrastructure, has issued a stark warning regarding the future of high-capacity storage: the era of petabyte-scale SSDs is rapidly approaching, and the traditional data protection methods that have served the industry for decades are no longer sufficient to ensure the safety of modern datasets.
At the heart of this concern is the sheer scale of upcoming storage deployments. In a detailed analysis prepared for Supercomputing 2026 (SC26), VAST Data presented the results of a massive simulation involving a 900-petabyte (PB) system. The findings were sobering. According to the company’s modeling, such a system, if managed by today’s standard parallel file systems and traditional RAID (Redundant Array of Independent Disks) configurations, would face a 1-in-11 chance of experiencing catastrophic data loss over a ten-year period.
This statistical vulnerability represents a significant departure from the historical "five nines" (99.999%) of reliability that enterprise and research institutions have come to expect. The shift is being driven by a physical reality of storage hardware: while drive capacities are increasing at an exponential rate, the bandwidth available to rebuild those drives following a failure is not keeping pace. This creates a widening window of vulnerability that threatens the integrity of the world’s most massive data repositories.
The Mathematics of the Rebuild Crisis
The primary issue identified by VAST Data stems from the relationship between drive capacity and recovery time. In a traditional RAID environment, when a single drive fails, the system must read data from the remaining healthy drives and calculate the missing information to write it onto a replacement drive. For decades, this process was relatively swift, occurring in a matter of hours.
However, as drives move toward the petabyte threshold, the "rebuild window" expands significantly. A drive that holds hundreds of terabytes or a full petabyte of data takes much longer to reconstruct than a 15-terabyte drive, simply because the physical interfaces and internal controllers can only move data so fast. During this extended rebuild period, the entire storage array is in a degraded state. If a second or third drive fails before the first rebuild is complete, the system can reach a point of "unrecoverable data loss."
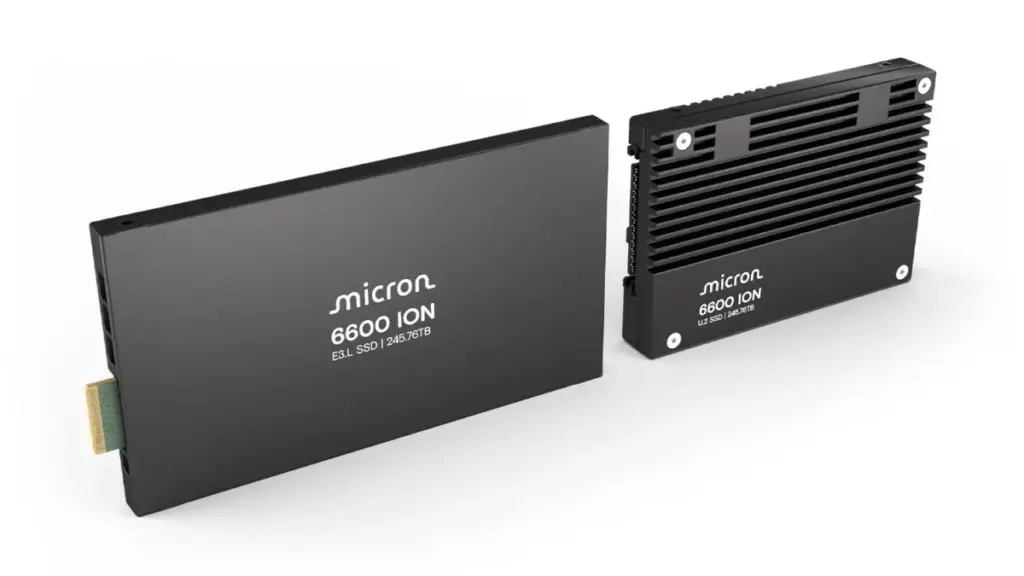
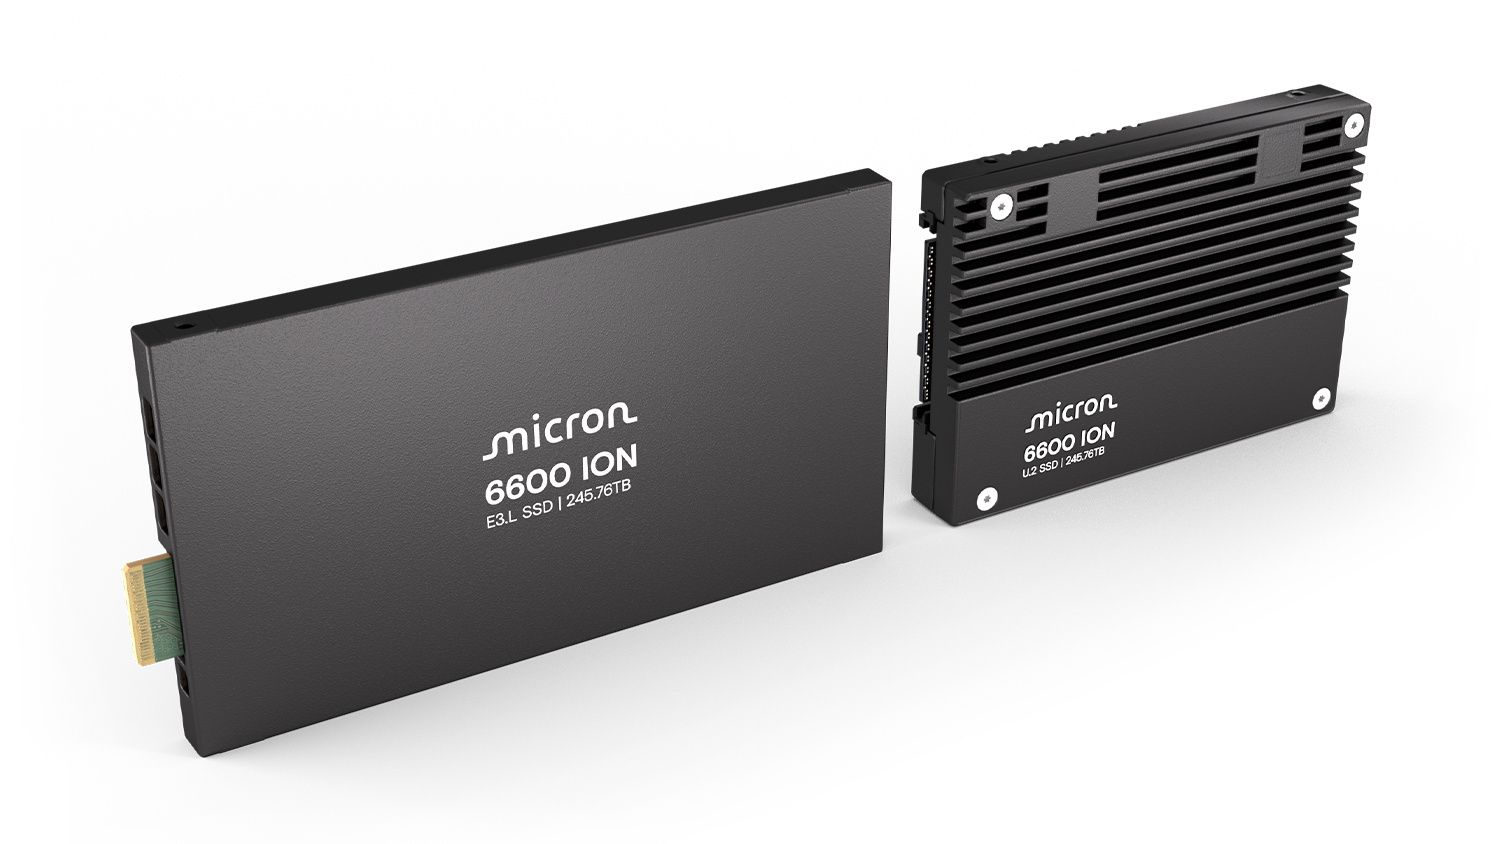
VAST Data’s simulation suggests that with the next generation of ultra-high-capacity SSDs—such as the 245TB Micron 6600 ION and its eventual successors—the probability of multiple concurrent failures becomes a statistical certainty rather than a remote possibility. When dealing with 900 petabytes of information, the sheer number of components involved increases the likelihood that a second failure will occur while the system is still struggling to recover from the first.
The Power Constraint Paradox
One might ask why data center operators would move toward such massive, high-capacity drives if they introduce such significant risks. The answer lies in the increasingly restrictive power and cooling budgets of modern data centers. As organizations rush to build out AI clusters, they are finding that available electricity is often the hardest resource to acquire.
 Hardware Reviews & PC Building
Privacy Concerns Surface for Meta’s Muse AI as Reports Suggest Unauthorized Access to Personal Messages
The rapid evolution of artificial intelligence has brought with it a wave...
 Hardware Reviews & PC Building
Digital Fly Brain Achieves 20 Percent Win Rate in Balatro Following Breakthrough Google Neural Mapping
In the rapidly evolving landscape of artificial intelligence and computational neuroscience, the...
 Hardware Reviews & PC Building
Intel Intensifies Restructuring Efforts with New Round of Global IT Layoffs
Intel Corporation is moving forward with another significant phase of its multi-year...







