
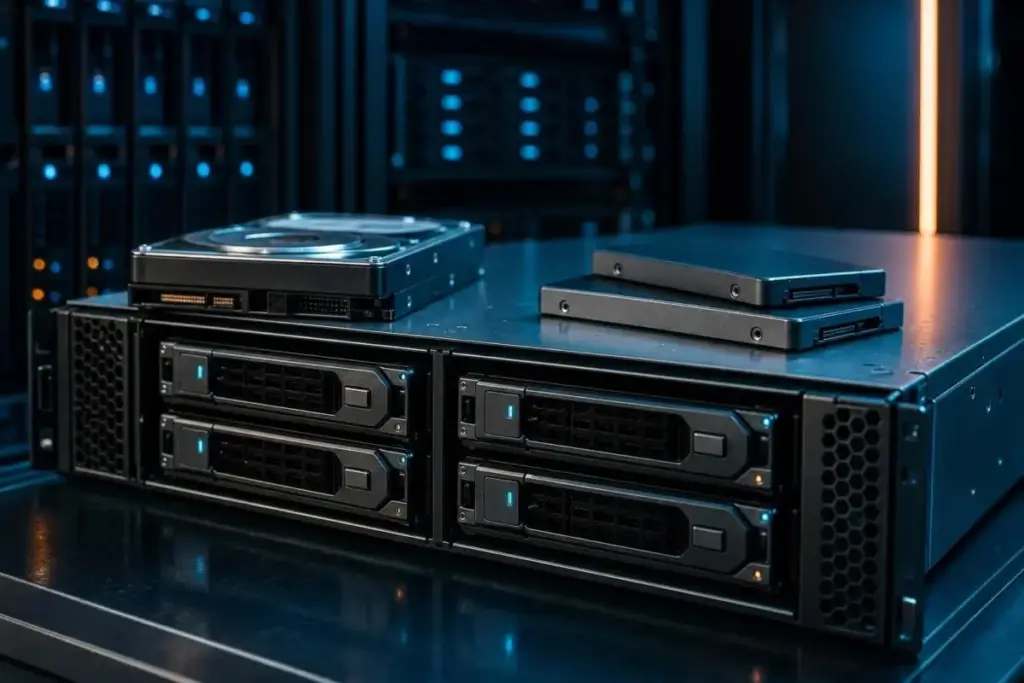
Comparing Redundancy Models: RAID 10, RAID 6, and RAID 1
When choosing a storage strategy, administrators often weigh RAID 10 against RAID 6 and RAID 1. Each offers a different balance of usable capacity, fault tolerance, and rebuild complexity.
RAID 1 is the simplest form of redundancy, consisting of a single mirror. While it provides excellent protection for small-scale deployments, it lacks the striping necessary for high-speed throughput. RAID 6, on the other hand, utilizes dual parity to protect against any two concurrent drive failures across the entire array. While RAID 6 is highly efficient in terms of capacity, it carries a significant performance penalty during write operations due to the need to calculate and write parity data.
The capacity gap between these levels is stark. In an array of eight 16 TB drives, a RAID 10 configuration yields only 64 TB of usable space—exactly 50% of the raw total. A RAID 6 configuration using the same drives would provide 96 TB of usable capacity. As drive counts scale into the dozens or hundreds, this "capacity tax" becomes a major budgetary consideration.
However, the performance trade-off often justifies the cost. RAID 10 writes each block to both mirror halves without the overhead of parity math. In contrast, RAID 6 must compute and write two parity blocks per stripe. Industry models suggest that RAID 10 carries roughly a two-fold write penalty, whereas RAID 6 can face a six-fold penalty. While these figures vary based on controller cache, stripe size, and workload types, the directional advantage of RAID 10 for write-heavy applications is well-documented.
Operational Realities of Drive Failure and Recovery
One of the most significant advantages of RAID 10 is the simplicity of its rebuild process. When a drive fails in a RAID 10 array, the system restores redundancy by copying data from the surviving mirror partner to a replacement disk. This is a straightforward I/O operation that does not require the intensive CPU cycles or complex parity recalculations associated with RAID 5 or RAID 6.
Because the rebuild is a direct mirror copy, it is generally less taxing on the overall array, allowing for more predictable performance while the system is in a degraded state. Nevertheless, administrators must remain vigilant. The "hard boundary" of RAID 10 is the mirror pair: if both disks in a single pair fail, that specific segment of data is lost, even if the rest of the array remains online.
This vulnerability highlights the difference between independent and correlated failures. RAID 10’s mathematical safety net assumes that disk failures are random, independent events. However, in a data center environment, drives often share a backplane, a power supply, or a specific firmware version. A power surge or a firmware bug could easily trigger the simultaneous failure of both members of a mirror pair. Experts recommend mitigating this risk by deliberately distributing mirror pairs across separate backplanes or enclosures, ensuring that a single component failure does not take down both sides of a redundant set.
 Enterprise Tech & Infrastructure
Navigating the Hidden Complexities of Amazon S3 Cost Management
For many enterprise IT departments, the monthly Amazon Web Services (AWS) bill...
 Enterprise Tech & Infrastructure
Understanding the Architecture of Modern Storage: Why the Choice Between Flash and SSD Is a Matter of Components, Not Categories
In the rapidly evolving landscape of enterprise data management, the terminology used...
 Enterprise Tech & Infrastructure
Upscale AI Challenges Nvidia’s Scale-Up Dominance with SkyHammer Fabric and $2 Billion Valuation
For decades, the architecture of high-performance computing was defined by a fiercely...







