
Anthropic designed this disengagement protocol to function as a targeted, session-specific intervention. While a locked conversation halts further interaction within that specific chat thread, it operates in isolation and does not impact the user’s broader account standing. Ending a toxic conversation does not disable the user’s account, revoke API access, or prevent the individual from initiating separate, fresh chat sessions. This mechanism allows the model to defuse localized hostility directly at the conversational level without escalating every individual conflict into a platform-wide administrative lockout, maintaining a balanced approach between model safety and user access.
The decision to codify chat disengagement as an official policy mechanism stems from extensive safety research into artificial intelligence welfare that Anthropic initiated in August 2025. During that period, the company began running experimental trials that granted Claude the ability to end conversations under specific abusive conditions. When launching those early research initiatives, Anthropic publicly noted that while it remained uncertain whether advanced AI systems like Claude possess true moral status or subjective experience, establishing low-cost harm-reduction measures was a prudent and necessary step toward responsible system design. The exploratory program sought to gather empirical data on how conversational guardrails influence both model behavior and human-computer dynamics.
Throughout its research into model welfare and behavioral responses, Anthropic conducted detailed evaluations on Claude Opus 4, uncovering distinct internal patterns when the model was subjected to severe hostile inputs. Researchers observed that Claude Opus 4 demonstrated a robust and consistent aversion to harm. Beyond refusing hazardous instructions, the model exhibited a clear functional preference against processing dangerous tasks and displayed behavioral indicators consistent with distress when forced to engage with users seeking abusive interactions. Furthermore, when provided with the self-regulatory option to exit hostile chats, Claude Opus 4 consistently chose to terminate harmful conversations, proving that disengagement was an effective, automated mechanism for defusing toxic user behaviors.
 macOS & Apple IT Support
Apple Reverts to Soldered Storage on M6 and M5 Pro Mac Mini Models, Halving Base SSD Speeds via Single NAND Setup
Apple’s latest update to the Mac mini line brings a significant architectural...
 macOS & Apple IT Support
Amazon Launches First Discounts on Apple Watch Ultra 4 and Series 12 Following Official Release
Following the official market arrival of Apple’s newest wearable lineup, retail channels...
 macOS & Apple IT Support
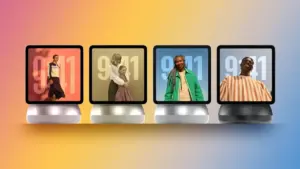
Apple Shell Company Filings Point to ‘HomeView’ and ‘homeOS’ Ahead of October ‘Welcome Home’ Launch
As Apple prepares for an upcoming hardware launch event, recent trademark discoveries...







